Mistral AI Releases Mistral Large 4 MoE Model
Mistral AI has launched a public preview of Mistral Large 4, a 1.05-trillion-parameter multimodal model that offers high-end cybersecurity capabilities without restrictive refusals.
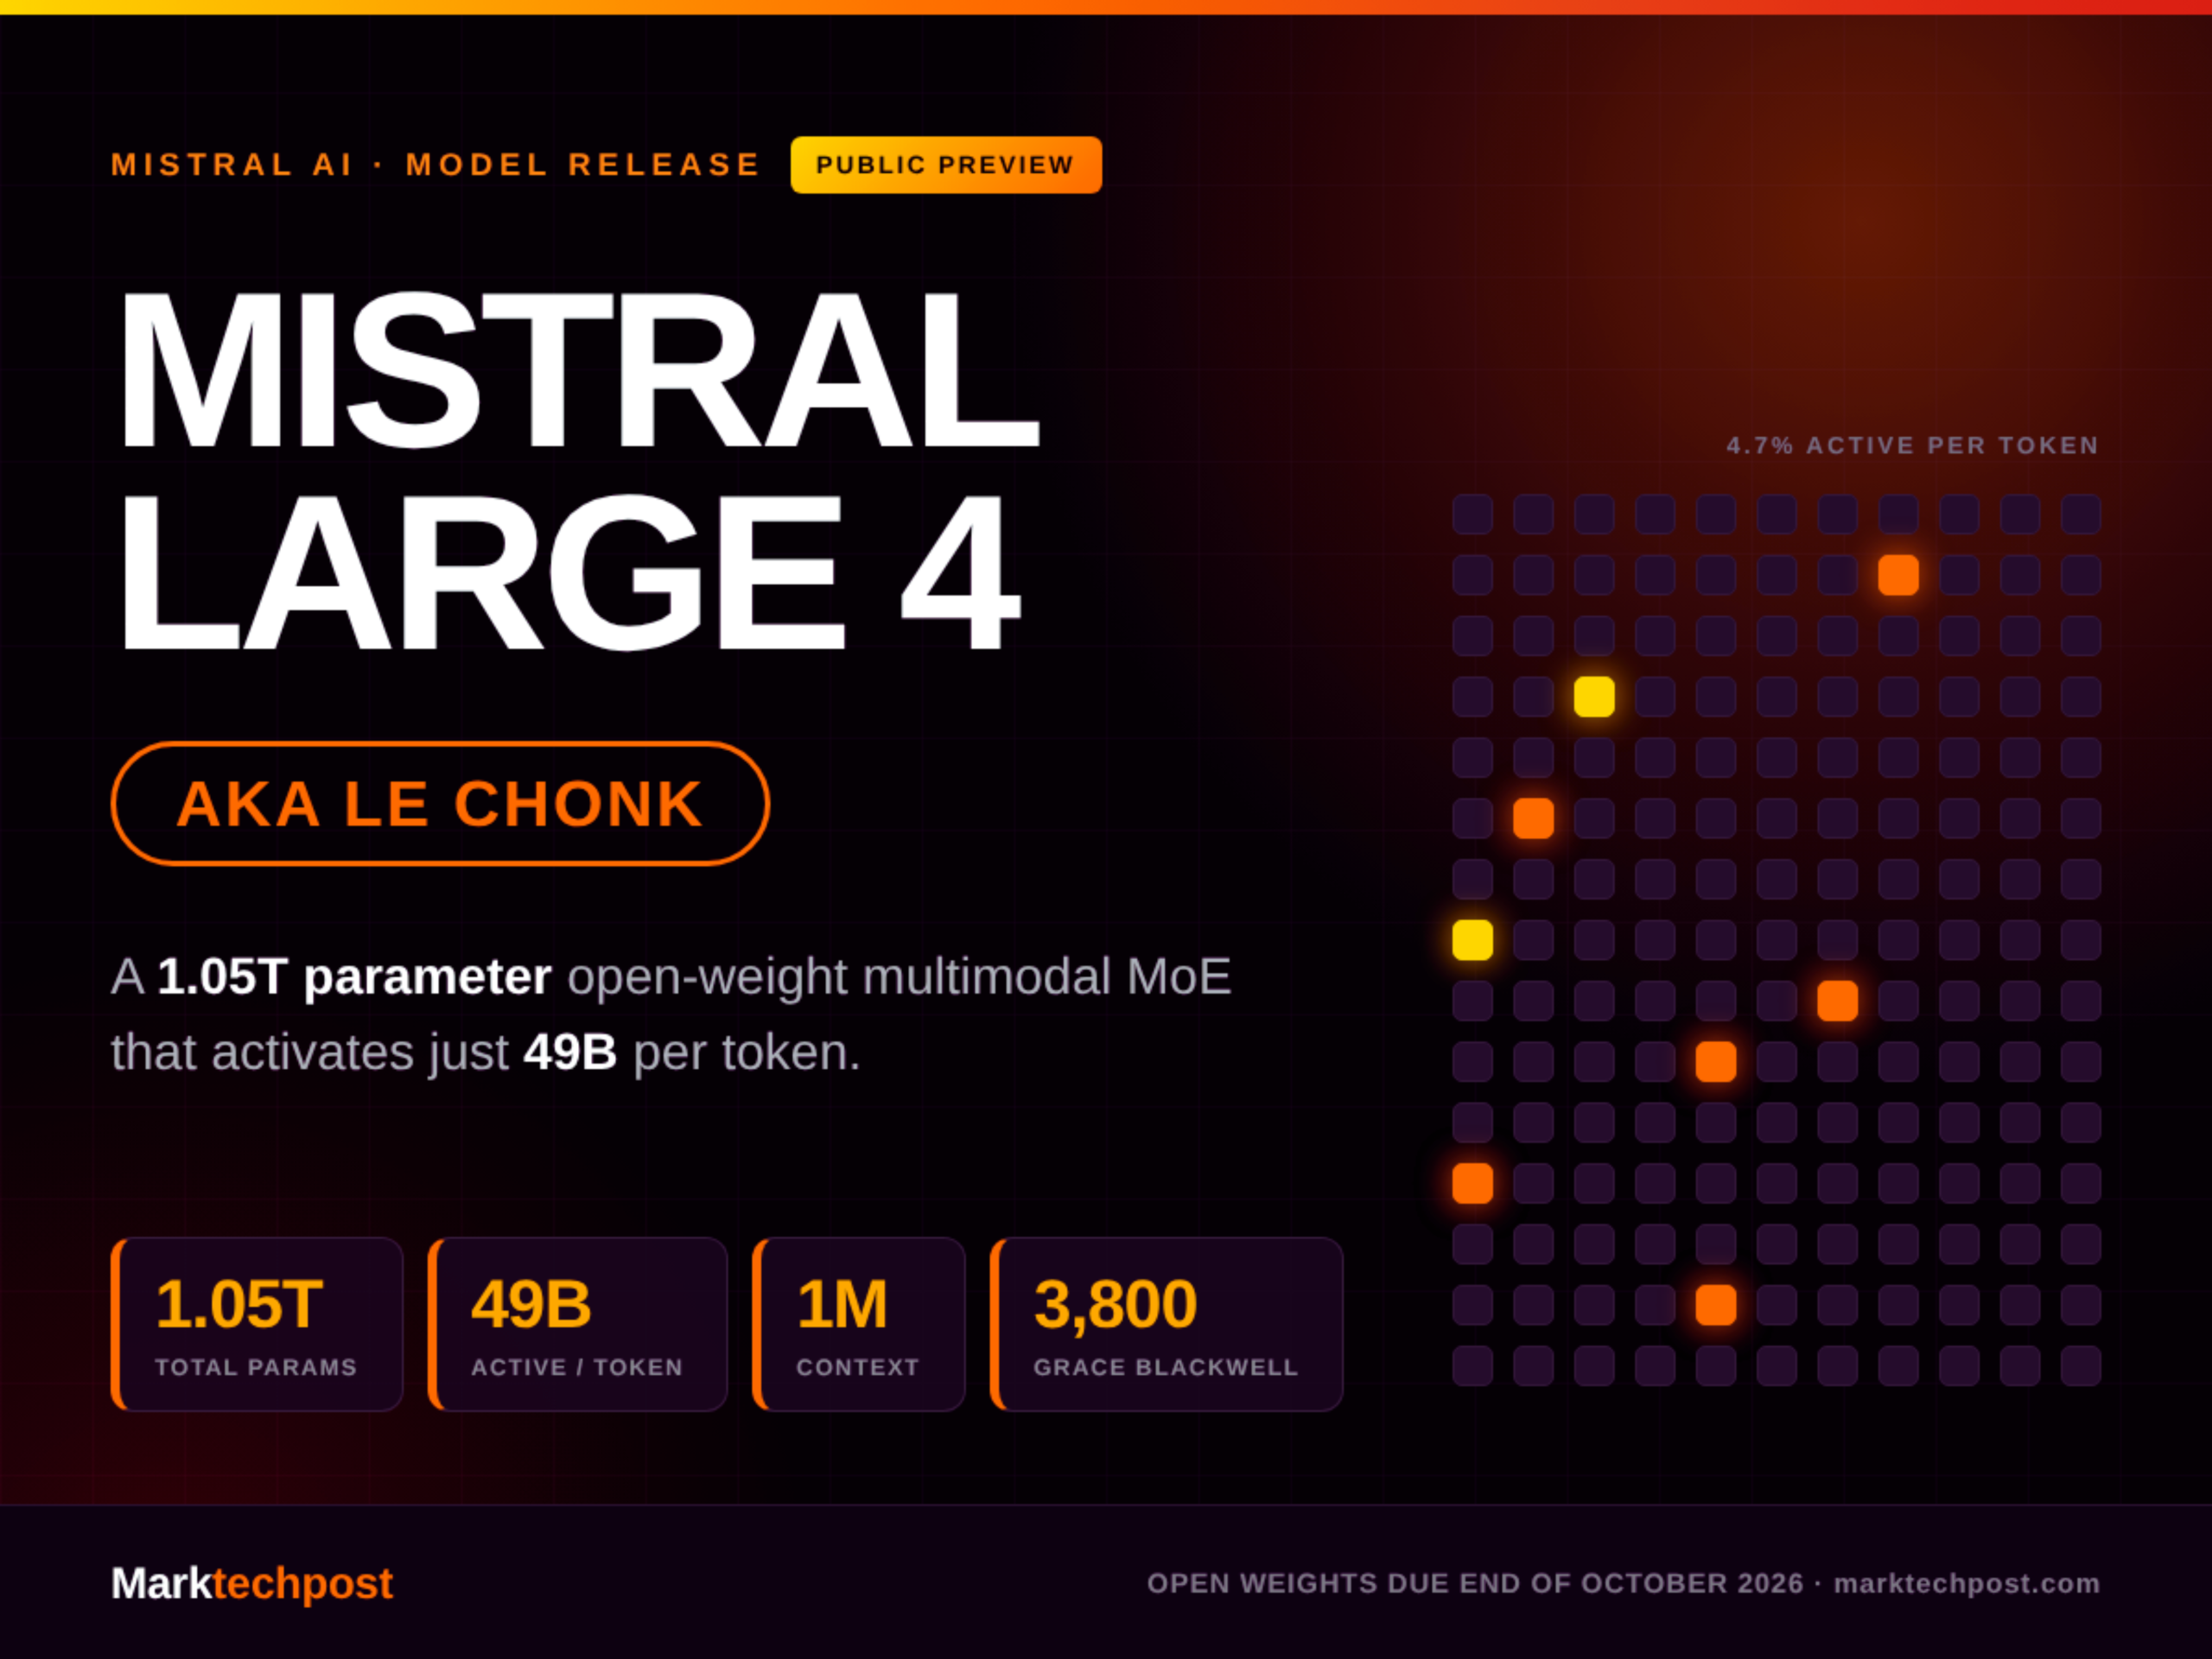
Mistral AI has launched a public preview of Mistral Large 4, internally dubbed "Le Chonk." This granular Mixture of Experts model features 1.05 trillion total parameters, with 49 billion active per token, alongside a 1.6 billion parameter vision encoder and a 1 million token context window. Trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs in Mistral's European datacenters, the hybrid instruct-and-reasoning model natively processes image inputs. Because only 4.7 percent of its weights activate per token, the model can be served at mid-tier pricing.
The model's API went live on October 6, 2026, supporting features like function calling, structured outputs, document QnA, batching, and the Agents and Conversations endpoints. Input tokens are priced at $1.36 per million, output tokens at $4.18 per million, and cached inputs at $0.14 per million. However, developers cannot self-host yet, as the weights will not be released until the end of October 2026.
Mistral Large 4 stands out in cybersecurity, scoring 93 percent on Cybench and 82 percent on CyberGym-E2E, securing a spot in the top five on the Artificial Analysis Cyber Index. Mistral notes that other frontier closed models score near zero on CyberGym-E2E because they refuse defensive tasks. In agentic coding, the model achieved 61.7 percent on DeepSWE v1.1, 59.4 percent on SWE-Atlas-QnA, and 28.3 percent on Terminal-Bench 4.0, yielding a combined Coding Agent Index of 49.8 percent. In a blind human evaluation by Surge AI, annotators rated the model 3.74 out of 5, placing it ahead of GLM-5.3 at 3.60 and Kimi K3 at 3.59, but behind Claude Opus 5 at 4.22. On safety, it resisted 93.3 percent of attacks on Lakera's B3 benchmark and scored 1.691 out of 2.0 on KORABench.
For practitioners, the model's low caching price of $0.14 per million tokens significantly alters the economics of running long-context agent loops. It also provides a powerful alternative to competitors like the 1.6-trillion-parameter DeepSeek V4 Pro, which has 49 billion active parameters, and the 2.8-trillion-parameter Kimi K3, which costs $3.00 for input and $15.00 for output per million tokens. For comparison, GLM-5.3 costs $1.40 for input and $4.40 for output. Mistral's training data spans over 160 languages, including all official European Union languages.
This is our own summary of reporting by MarkTechPost